Skip to content

Compute · Dedicated GPU nodes

Dedicated GPU nodes for AI teams. Yours alone for the term.

Whole NVIDIA nodes reserved for your team on a 1, 2 or 3-year term and configured to your workload. Run them on bare metal or on managed Kubernetes and Slurm. Serve your own models, or resell the capacity under your brand.

8 GPUs per node · NVIDIABare metal or managedSteady power, backed by firmingStatic IPs · uplink
Term
1, 2 or 3 years, set per deal
Tenancy
Single-tenant. Whole nodes, yours alone
Stack
Bare metal, managed Kubernetes or Slurm
Hardware
Configured to your workload

How it works

From first call to your cluster.

One capacity agreement covers the whole path, from the spec to the last day of the term.

  1. Before handover · we build

    01

    Scope

    GPU, node count, network, storage and term. We come back with a proposal.

  2. 02

    Sign

    One capacity agreement for the whole term.

  3. 03

    Build and burn-in

    We rack, cable and power the nodes, then stress-test every GPU before you see it.

  4. 04

    Acceptance

    You run your own tests against criteria agreed at signing. Nodes that fail are fixed or replaced.

  5. From handover · your term

    05

    Handover

    The nodes join your cluster and your term starts.

  6. 06

    The term

    We run the hardware and the site. You run your models, or sell the capacity.

Term, price, delivery date, uptime commitments and support are agreed per deal.

Talk to sales →

Your stack, or ours

Run it the way your team already works.

Your ML engineers get the environment they already use. Your compute team gets nodes that are theirs alone.

Bare metal
Full root on whole servers. No hypervisor between your code and the GPUs.
Managed Kubernetes
A cluster we set up and keep running, ready for your inference and training workloads.
Slurm
Managed Slurm for batch jobs and training runs, on the same nodes.
Storage
Local NVMe on every node, plus shared storage sized to your models and data.

The hardware

Built to your spec.

Tell us the GPU, the cluster size and the network your models need. We configure the nodes around your workload, not a fixed catalog.

GPUs
Current NVIDIA data center GPUs, chosen with you for your models
Scale
From a few nodes to full clusters, with room to add more on the same site
In the node
NVLink between the GPUs of each node
Between nodes
InfiniBand or Ethernet fabric, sized to how your nodes work together
Storage
Local NVMe plus shared storage, sized to your data
Access
Bare metal with full root, or managed Kubernetes and Slurm
Power
Steady power, backed by firming
Region
Latin America, on sites we build and operate

Terms

A term that fits your roadmap.

Choose 1, 2 or 3 years for each deal. A shorter term keeps you on current hardware; a longer one lowers the rate.

01

Renew

Keep the same nodes for another term, at a rate set at renewal.

02

Move up

Take the next GPU generation on a new term, on the same site.

03

Hand back

Return the nodes when the term ends.

Why teams trust the nodes

Built and run by the same team.

We generate and firm the power, build the sites and run them ourselves. Nobody else sits between your nodes and the people who fix them.

2022

First site energized. Operating ever since.

~25 MW

Of compute built and running today.

4 sites

Built and run by our own field team.

2.5 GW

Of sites in development.

Steady power
Dedicated nodes run on the site’s steady band, backed by firming, never on the variable layer.
Our own crew
Our technicians run the sites around the clock and keep spare parts on hand.24/7 staffing to confirm
A named engineer
One engineer stays with your team from scoping through handover and the whole term.to confirm
Security
Fenced, monitored sites with controlled access. Compliance reports shared under NDA.add SOC 2 / ISO status once held

Placeholder: customer logos and a short case study go here once customers can be named.

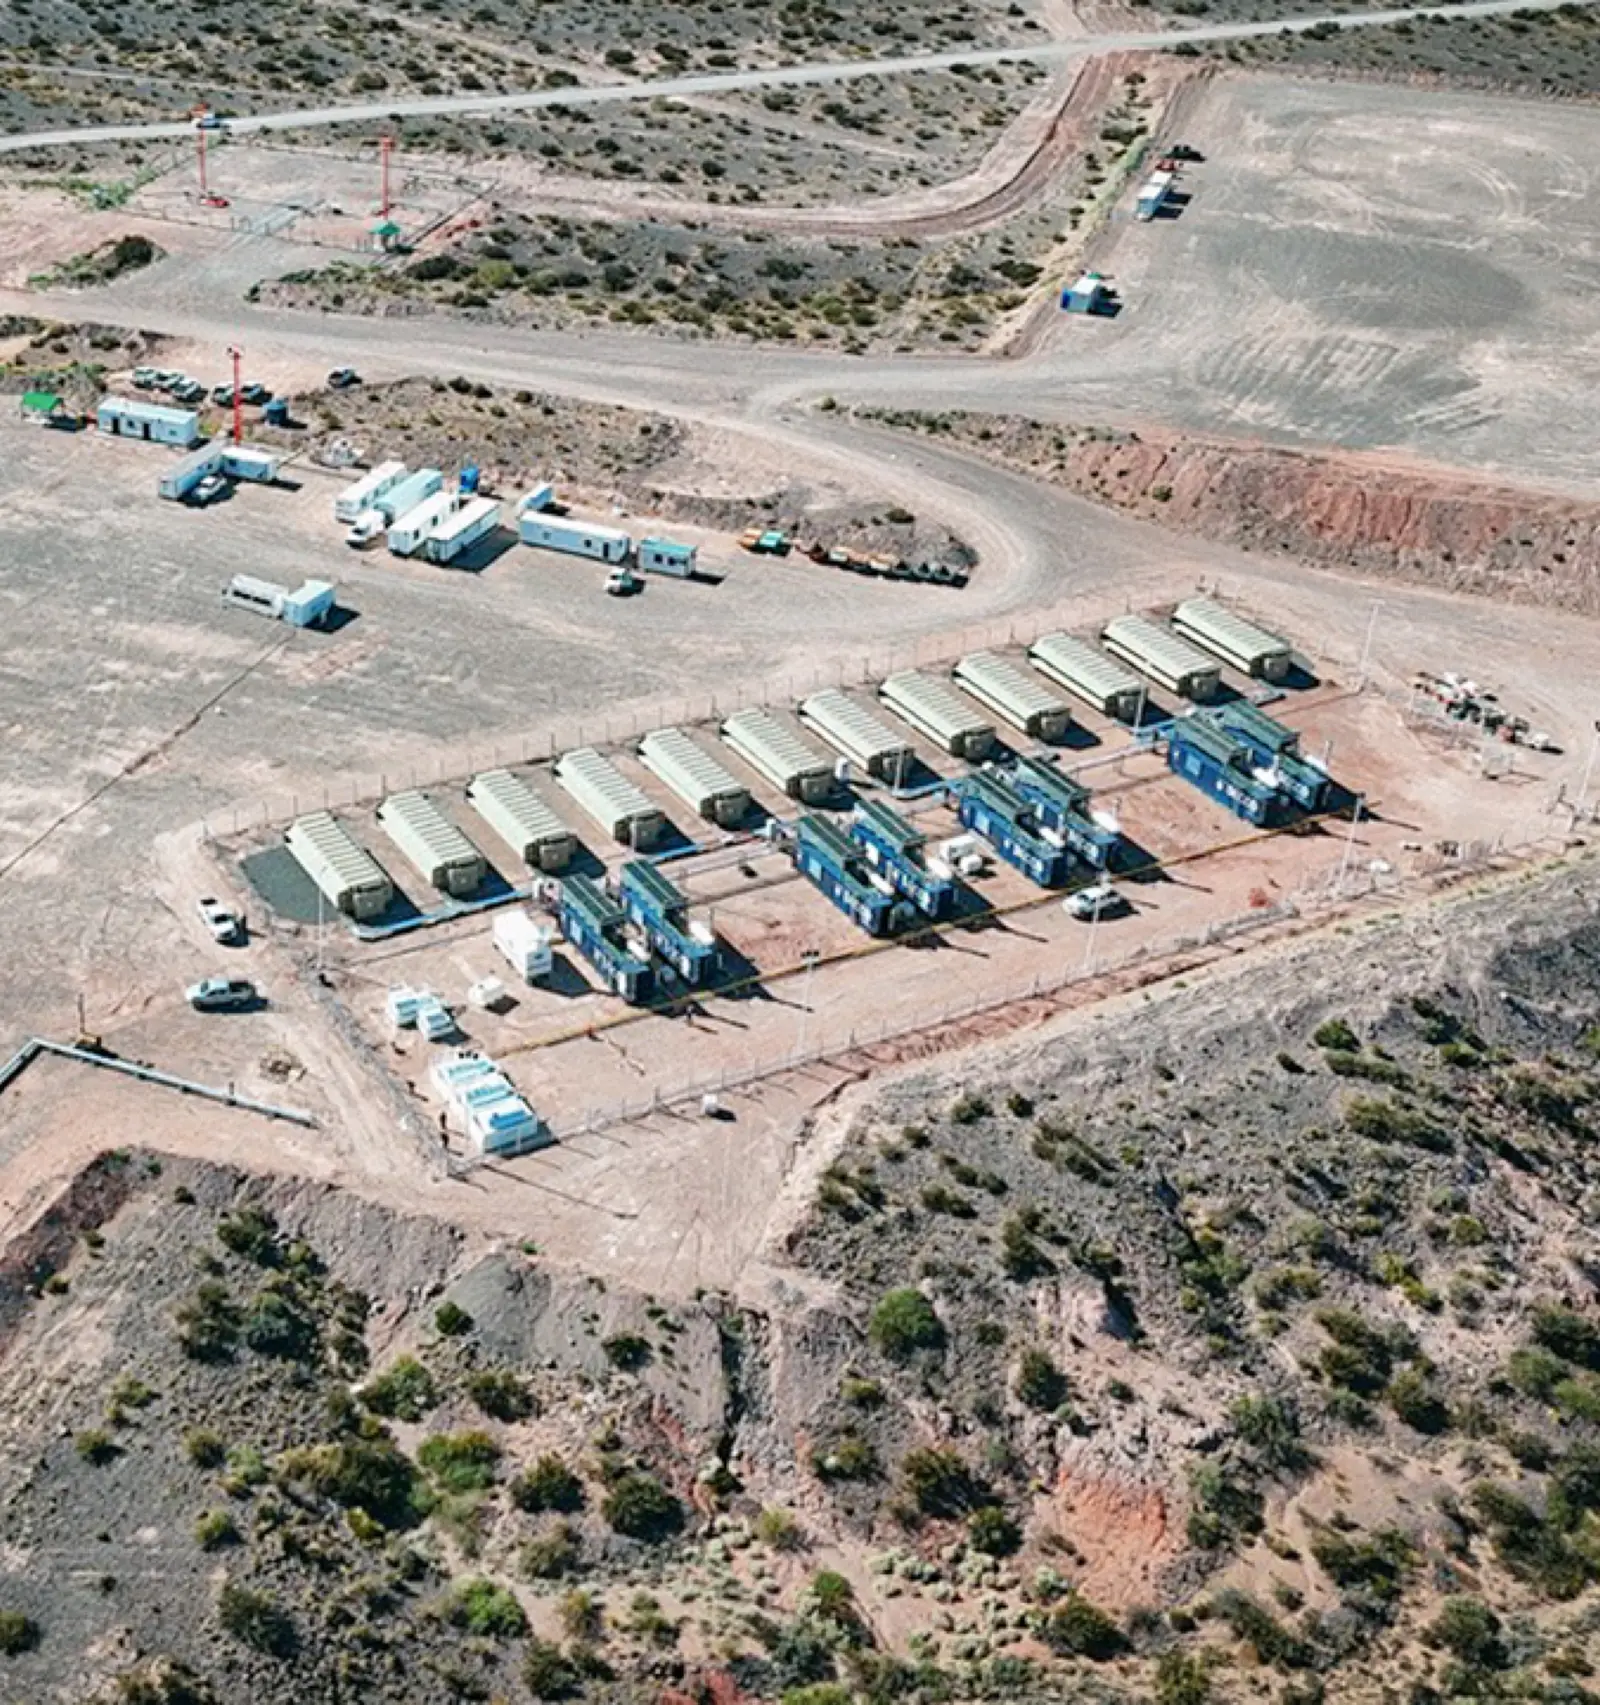
Aerial view of the Los Toldos II site: rows of compute modules on a gravel pad in the Patagonian steppe.

Sites we build and run ourselves.

Los Toldos II · one of our operating sites

Also on the same site

Two more ways to buy.

Add interruptible compute on top of your dedicated nodes, or bring GPUs you already own.

The variable layer

Interruptible compute

30–50% below dedicatedto confirm

Runs on the site’s variable power. It pauses only for energy reasons, with notice first, then resumes. Suits batch work, evals and checkpointed training.

Fits batch inference, evals, background agents

Your GPUs, our power

Bring your GPUs

Per kW-month · power includedrate to confirm

Powered colocation for hardware you own. We supply the energy, the site and the operations, without the wait for grid-connected colo.

Fits platforms with their own GPU fleet

FAQ

Compute questions.

Who owns the hardware?+

We do. We own and operate the GPUs and the sites. Your team gets exclusive use of the nodes for the term, without putting them on your balance sheet.

Can we choose the hardware?+

Yes. Tell us the GPU, node count, network and storage your models need, and we configure the nodes around them.

Do you offer managed Kubernetes or Slurm?+

Yes. Take the nodes as bare metal with full root, or run them on managed Kubernetes or Slurm, with shared storage.

How long is a term?+

1, 2 or 3 years, chosen per deal. At the end you can renew, move to the next GPU generation, or hand the nodes back.

What happens when a GPU fails?+

Our crew swaps the failed part from spares kept on site. Replacement times and uptime commitments are agreed in your contract.

Can we resell the capacity?+

Yes. You can resell, white-label or bundle it under your own brand, at your own prices.

Can we start small and add nodes later?+

Yes. Tell us the node count you need now and we will give you a delivery date. More nodes can join on the same site later, on their own term or ending with your first.

Can we add cheaper capacity on top?+

Yes. Interruptible compute runs on the site’s variable power at a lower rate, with notice before any pause. It suits batch tiers and work that can wait.

Where do the nodes run?+

In Latin America, on sites we build and operate. We share the exact site and network routes during scoping. On bare metal, only your team has access to the operating system and your data.

contact us

Talk to sales

Tell us about the workload, the GPUs, how many nodes, when you need them and the term. We reply with a proposal.

We reply within 48 hours. [email protected]